Linear regression from scratch: OLS, the design matrix trick, and QR decomposition
Linear regression is one of the simplest models in machine learning. It is usually one of the first algorithms encountered in most conventional machine learning courses, with its final form deceptively straightforward: take some input variables, multiply them by a set of coefficients, add an intercept, and obtain a prediction. But when working on complicated research problems, sometimes the standard recipe is not quite fit for purpose, and one needs to modify the method or implement parts of it from scratch, which means having a handle on the maths. (I also think there is value in doing this more generally. With most high-level libraries hiding much of the underlying mathematics, keeping at least one hand on the maths at all times is important for maintaining rigour).
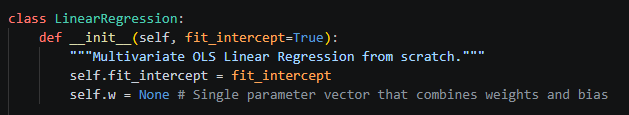
So let's talk about implementing linear regression from scratch. Since I am a little bit short on time this week, we'll constrain our discussion by focusing on the simplest approach: ordinary least squares (OLS). We'll start from the mathematical model and then connect each part of that model to a NumPy implementation. A useful trick that we'll use is to absorb the intercept into the parameter vector, using what is known as the design matrix trick, and then solve the least-squares problem analytically using QR decomposition.
Linear regression
Suppose we have \(n\) observations and \(p\) explanatory variables. For a single observation, the usual linear regression model is
\[ y = \beta_0 + \beta_1x_1+\cdots+\beta_px_p+\varepsilon. \]
The intercept \(\beta_0\) is slightly awkward here because it sits separately from the other parameters. In vector notation we might instead write
\[ y = x^Tw+b+\varepsilon, \]
where \(w\) contains the coefficients and \(b \) is the intercept.
There is a simple way to absorb \(b \) into the same linear-algebraic machinery as the other parameters. We prepend a \(1 \) to the feature vector,
\[ \tilde{x}=\begin{pmatrix}1 \\ x_1 \\ \vdots \\ x_p\end{pmatrix} \]
and define a new parameter vector
\[ \theta=\begin{pmatrix}\beta_0 \\ \beta_1 \\ \vdots \\ \beta_p\end{pmatrix} \]
Then, notice we may write
\[ y=\tilde{x}^{T}\theta+\varepsilon. \]
For \(n \) observations, this amounts to prepending a column of ones to the original feature matrix \(X \) so that we have
\[ \tilde{X}=\begin{pmatrix}1 & x_{11} & \cdots & x_{1p} \\ 1 & x_{21} & \cdots & x_{2p} \\ \vdots & \vdots & & \vdots \\ 1 & x_{n1} & \cdots & x_{np} \\ \end{pmatrix} \]
The entire model then becomes
\[ y=\tilde{X}\theta+\varepsilon. \]
This is the design matrix trick. What was originally an affine map, \( Xw+b, \), has been converted into the purely linear map \( \tilde{X}\theta. \) It is a small change, but quite a useful one because the intercept no longer requires any special treatment.
Ordinary least squares
OLS chooses the parameter vector which minimises the squared residuals,
\[ \hat{\theta} = \arg\min_{\theta} \left \Vert y-\tilde{X}\theta\right \Vert_2^2. \]
Expanding the objective gives
\[L(\theta) = (y-\tilde{X}\theta)^\top(y-\tilde{X}\theta)\]
Differentiating with respect to \(\theta\) and setting the gradient to zero gives the normal equations
\[ \tilde{X}^{\top}\tilde{X}\hat{\theta} = \tilde{X}^{\top}y \]
Provided the design matrix has full column rank, this gives the familiar expression
\[ \hat{\theta} = (\tilde{X}^\top\tilde{X})^{-1}\tilde{X}^{\top}y \]
It is worth making one distinction here. Nothing about this optimisation problem inherently requires Gaussian errors. OLS, at this level, is a geometric problem: we are finding the vector \(\tilde{X}\hat{\theta}\) in the column space of \(\tilde{X}\) which is closest to \(y\).
Probabilistic assumptions become relevant when we want to interpret the estimator statistically — for example, when relating OLS to maximum likelihood or constructing classical confidence intervals.
From the mathematics to NumPy
Implementing the design matrix is relatively simple:
def _prepare_design_matrix(self, X):
    X = np.asarray(X, dtype=np.float64)

    if self.fit_intercept:
        n_samples = X.shape[0]
        return np.hstack((np.ones((n_samples, 1)), X))

    return X
If \(X\) originally has shape \(n\times p\), the augmented matrix has shape \(
n\times(p+1). \) The first component of the fitted parameter vector is therefore the intercept, while all remaining components are the feature coefficients.
One could now implement the closed-form expression above directly. Numerically, however, explicitly computing \((\tilde{X}^\top\tilde{X})^{-1}\) is generally a highly sub-optimal way to solve a least-squares problem. Apart from the unnecessary computational overhead of matrix inversion, forming the normal-equation matrix squares the condition number
\[ \kappa(\tilde{X}^\top\tilde{X}) = \kappa(\tilde{X})^2, \]
which can substantially amplify numerical sensitivity if the design matrix is already poorly conditioned. Instead, we can work with the design matrix directly using QR decomposition, \( \tilde{X}=QR, \) where \(Q\) has orthonormal columns, so that \(Q^\top Q=I\) and \(R \) is upper triangular. The least-squares problem can then be reduced to solving
\[R\hat{\theta}=Q^\top y\]
So rather than constructing and inverting \(\tilde{X}^\top\tilde{X}\), we can write the computation as
Q, R = np.linalg.qr(X_design, mode="reduced")
Qty = Q.T @ y
theta = np.linalg.solve(R, Qty)
For the overdetermined, full-column-rank case considered here, this gives the analytical OLS solution while avoiding an explicit matrix inverse.
The complete fitting step is consequently quite small: construct the design matrix, put the target into column-vector form, perform the QR decomposition, and solve the resulting triangular system.
Prediction then reduces to exactly what the mathematics suggests, namely
y_pred = X_design @ theta
A useful exercise in looking below the API
Libraries such as scikit-learn hide most of these details when we perform computations such as fitting a linear regression model. In many cases, that abstraction is entirely sufficient. At a research level, however, relying only on prefabricated algorithms is not always adequate. This is one of the reasons I think there is considerable value in approaching machine learning from the mathematical side. Mathematics provides a way of reasoning about a model independently of any particular implementation. In practice, one cannot always simply plug an existing algorithm into a problem unchanged: sometimes the method needs to be modified, extended, or rebuilt around the particular structure of the problem. Once that structure is clear mathematically, the code becomes an expression of it rather than merely a collection of library calls.
Even in the case of something as simple as linear regression, implementing the model from scratch can provide intuition that stretches beyond the immediate. One sees how the intercept is just another coordinate once the feature space is augmented; fitting becomes a least-squares problem; and prediction is ultimately a matrix-vector product. Moving beneath the abstraction also exposes ideas from geometry, optimisation, and numerical linear algebra that are easy to overlook when working only through a high-level interface. More generally, developing this mathematical intuition makes it easier to understand what an algorithm is actually doing, and to reason about how it should be adapted when adaptation to a particular problem is needed.